Find the evidence that matters to your hiring decision.
Review applications against the role and your hiring criteria. Find strengths, concerns, and unanswered questions sooner, with supporting evidence you can check. You decide whom to interview.
Apple Silicon Mac · 14 days or 50 completed evaluations, whichever comes first.
Your own OpenAI API key is required. Set up your OpenAI API key. OpenAI usage is billed separately, with no CandidTalentEdge markup. View Pro pricing and checkout on Polar A Pro license activates on up to three of your Macs.
Observed OpenAI cost: US$0.08 to US$0.15 per candidate
In my own use, initial résumé parsing and one evaluation together have typically cost US$0.08 to US$0.15 per candidate. Based on CandidTalentEdge v1 using its recommended model, gpt-5.6-terra, in September 2026. Actual costs vary. Re-evaluations incur additional usage costs, and the CandidTalentEdge license is separate.
See what deserves a closer look.
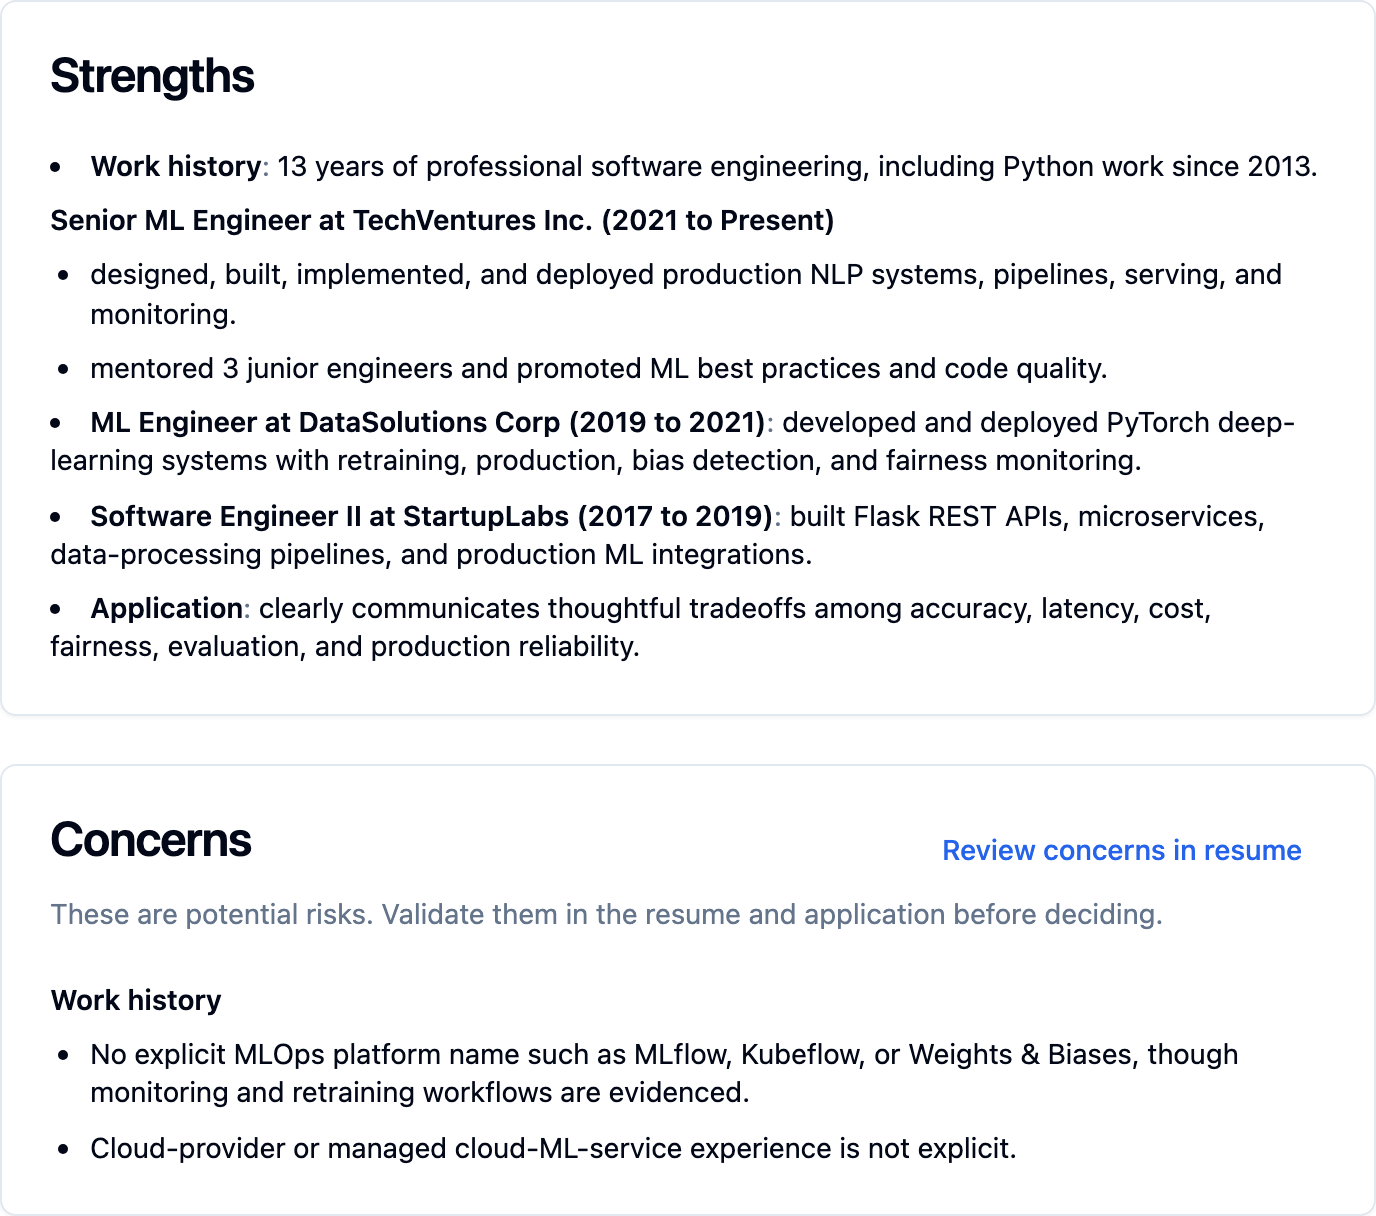
A rating gives you a starting point. The evidence helps you decide whether you agree.
Keep your reasoning with the review.
Record why you agree or disagree with a finding, alongside the candidate’s review. When you return to the application, you can see what informed your decision.
For internal recruiters, the evidence gives you a concrete basis for discussing with the hiring manager why someone deserves a closer look and which requirements need clarification.
Turn unknowns into better questions.
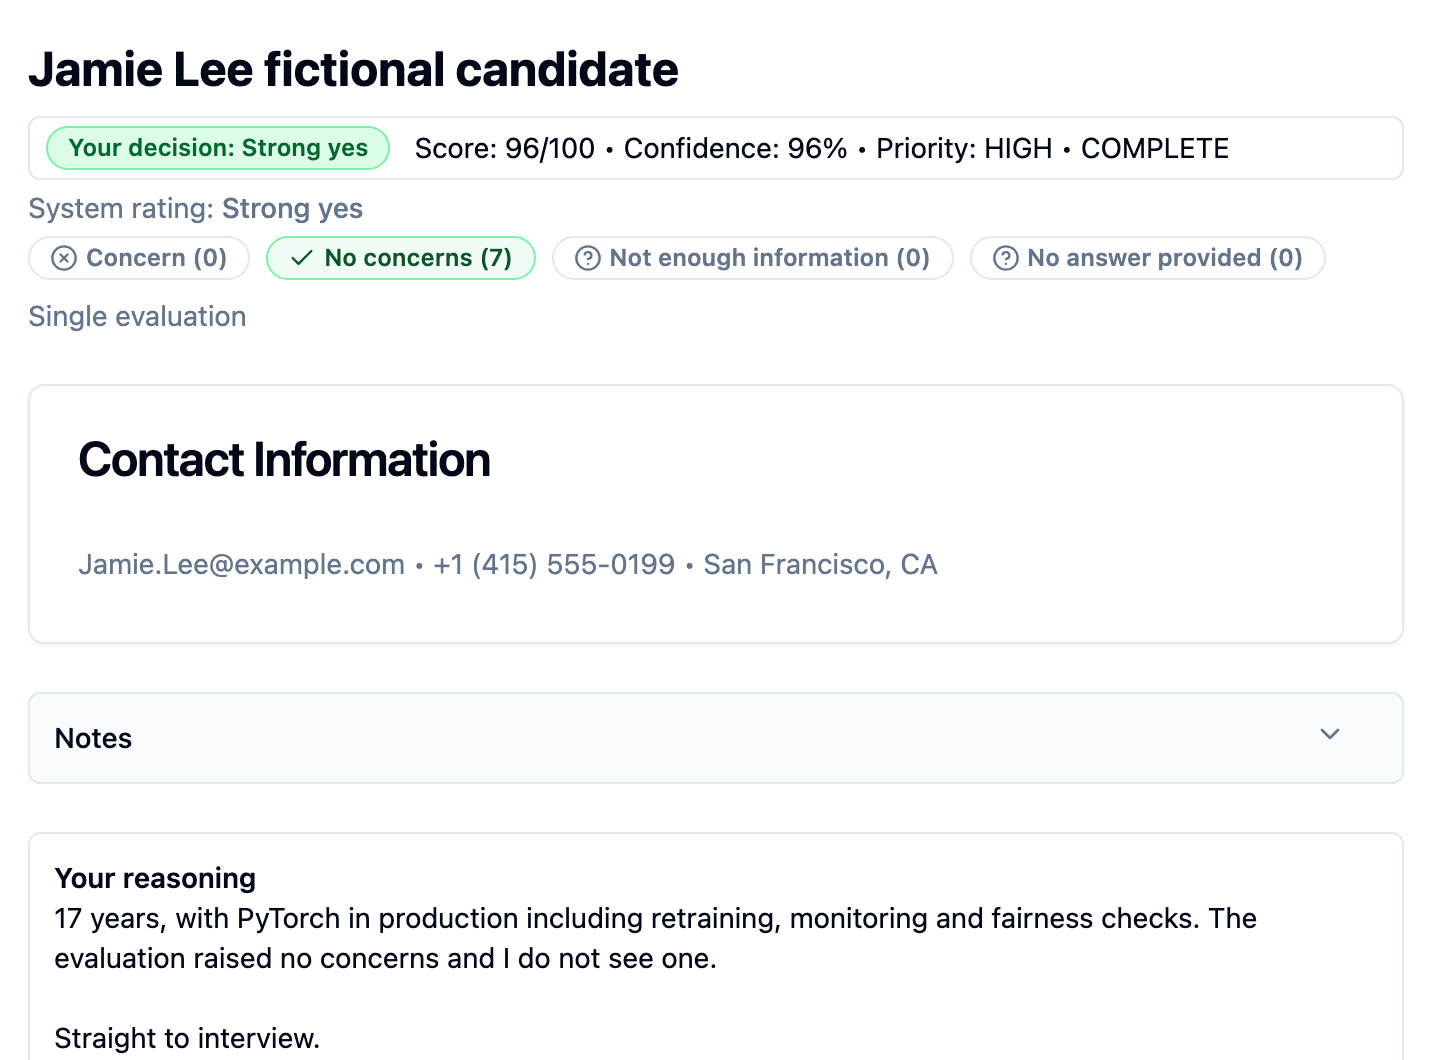
Review gaps, contradictions, and concerns against your criteria. Missing information stays an explicit unknown, giving you something concrete to explore in an interview.
A concern is a reason to look closer. It is not an automatic hiring decision.
The application shows model development and deployment work, but the review leaves the production machine-learning experience criterion unresolved.
Summarized from the fictional example shown here.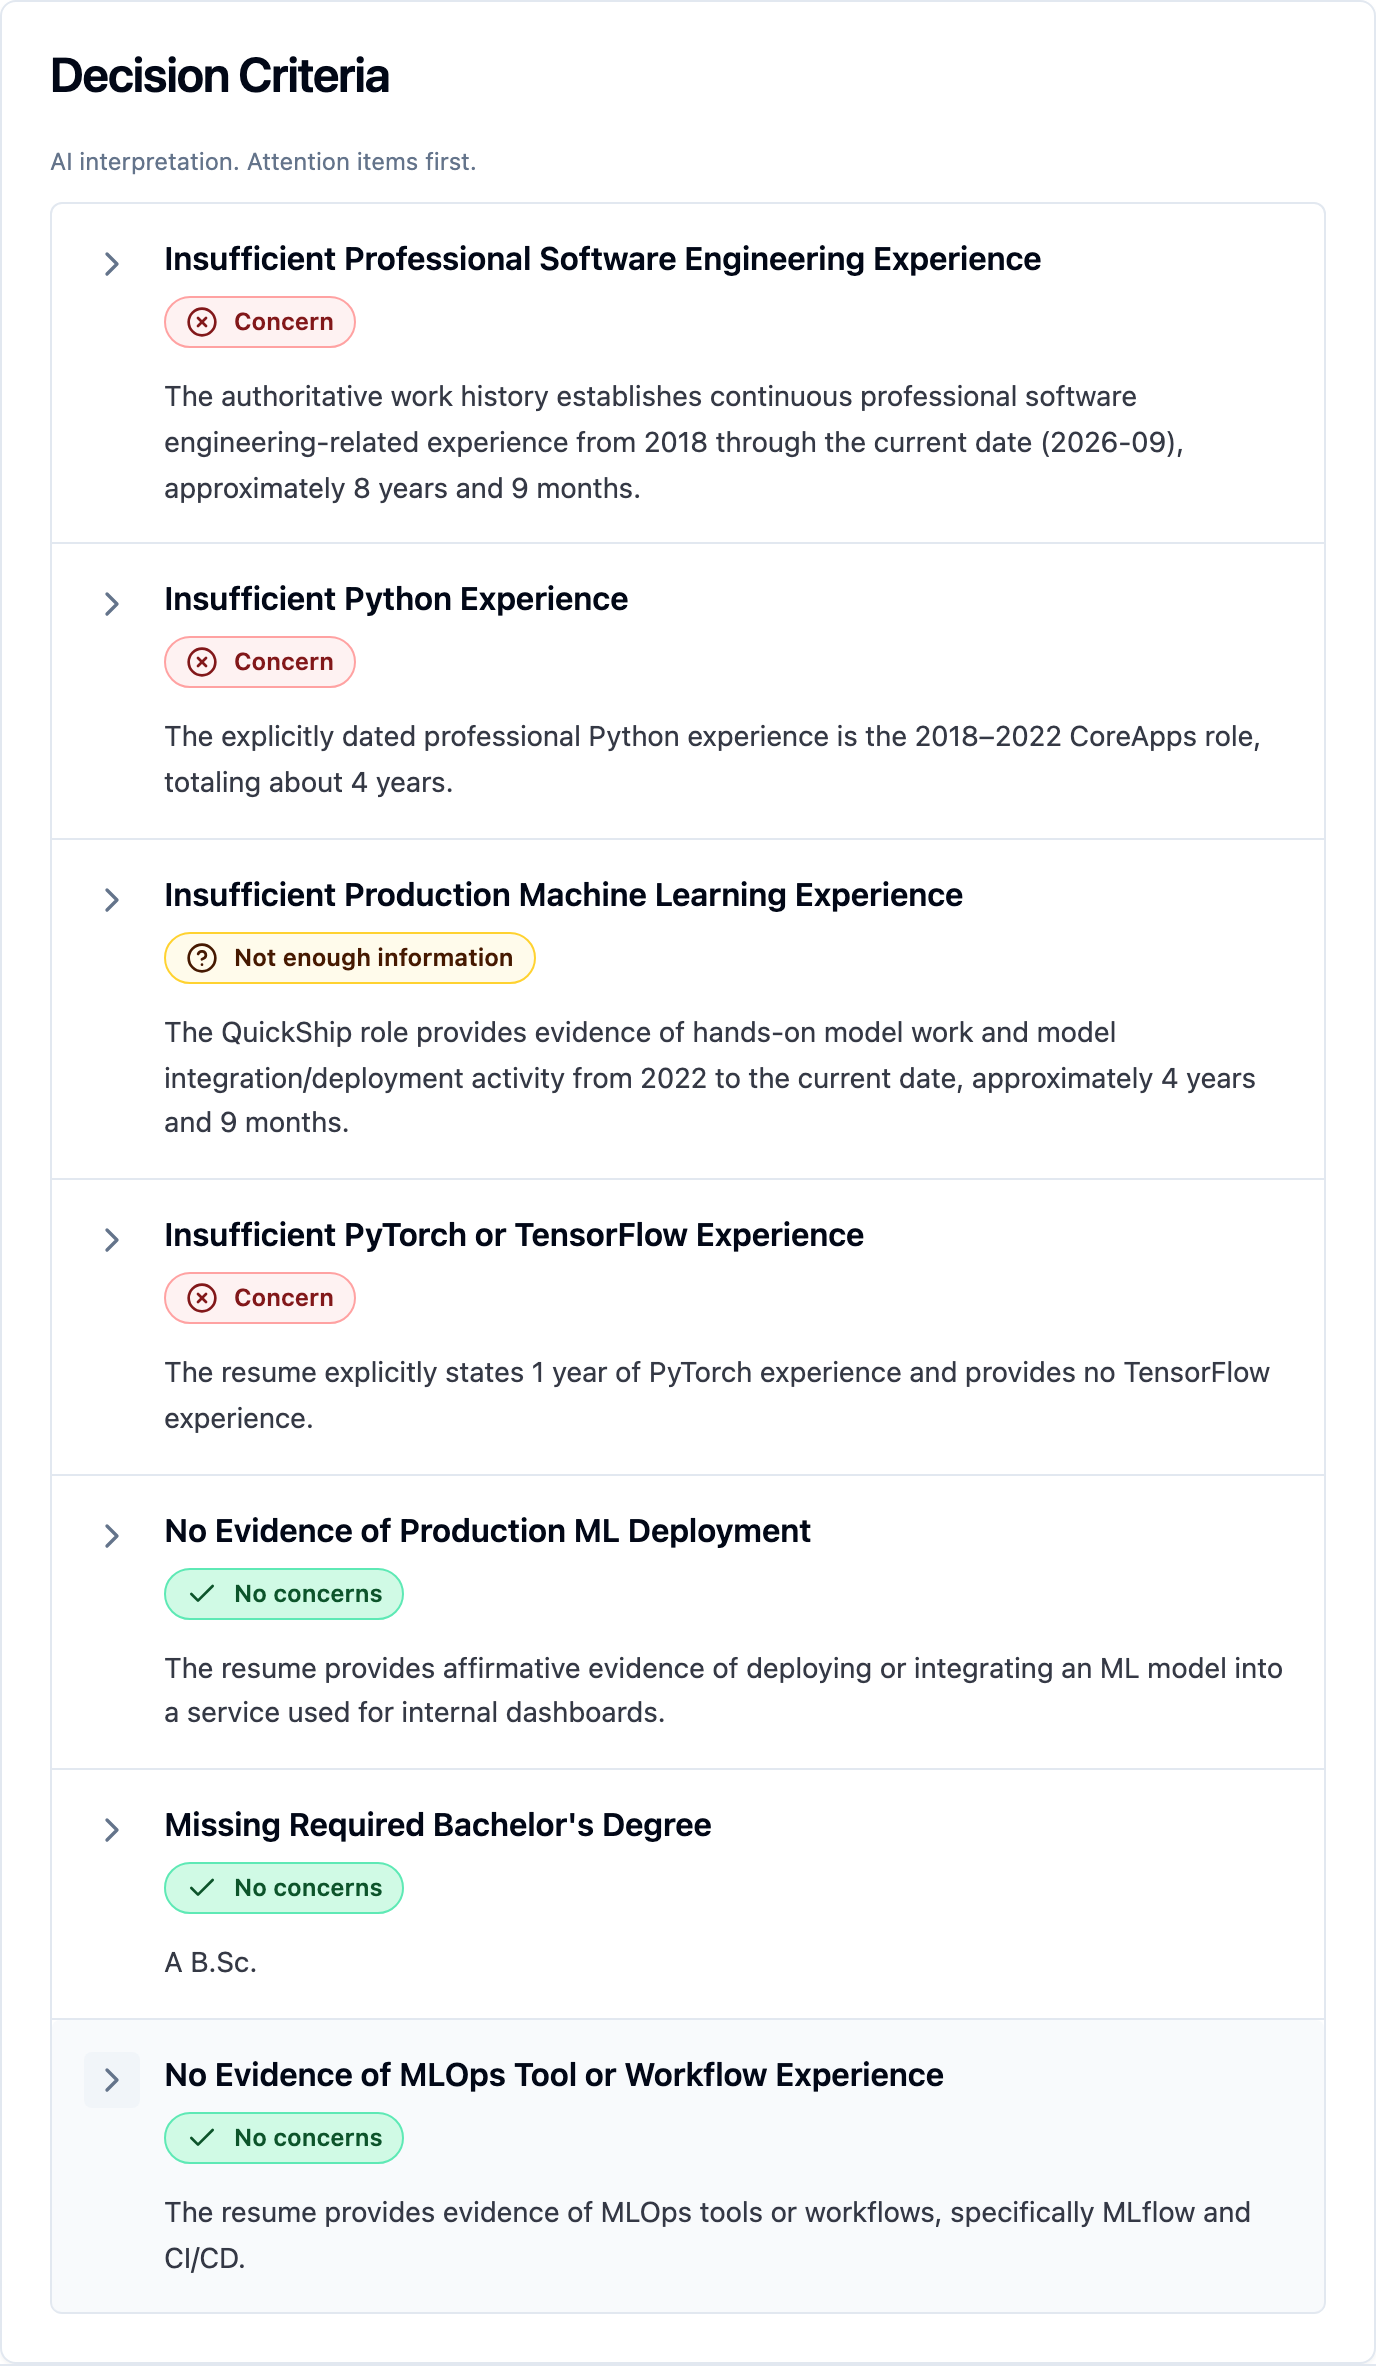
Record your own decision.
Keep your decision separate from the system rating. Record agreement or disagreement, review the evidence, and decide which candidates deserve more of your attention.
Every applicant you add is reviewed against the same criteria for the role, regardless of arrival order.
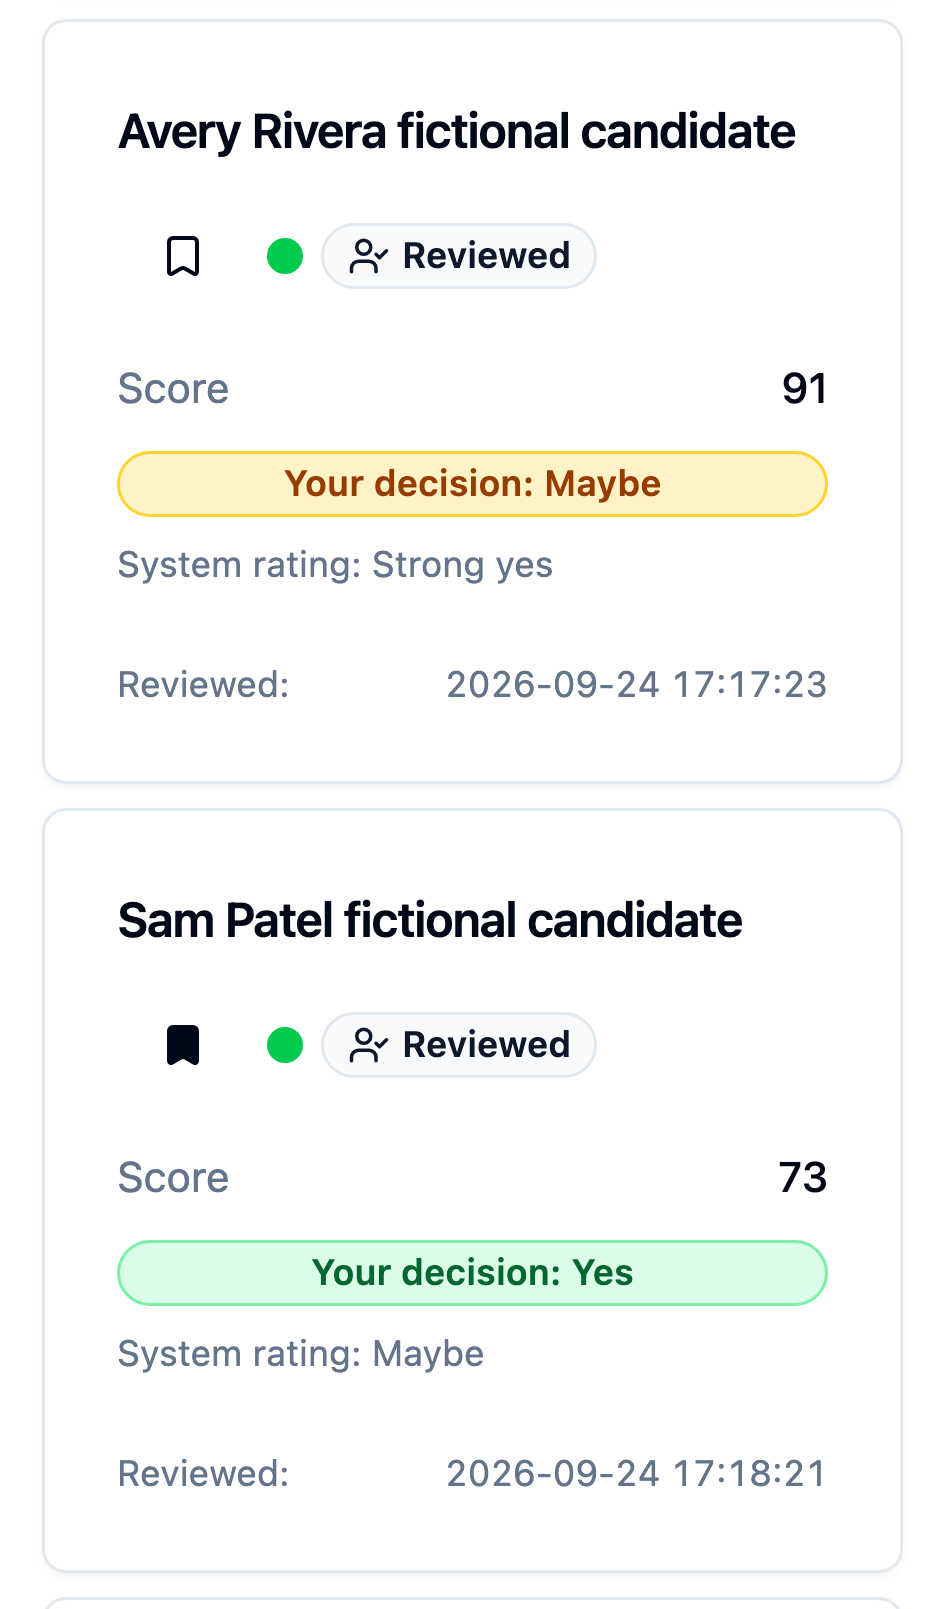
Set up the review around how you hire.
Define the experience and qualities you value for this role. Review and approve the screening criteria before applying them to candidates.
Describe the role.
Add the job description, ideal-candidate context, and warning flags that matter to your review.
Choose your criteria.
Edit, approve, or skip suggested screening filters before use.
You can also start without custom filters. If you reject a candidate because they don’t meet a job requirement, turn that reason into a filter. Review and approve it before applying it to other candidates.
Review the findings.
Add candidate materials. Examine strengths, concerns, unknowns, and evidence against the role.
Use the same process whether you have a few applicants or hundreds.
Why not just use ChatGPT or Claude?
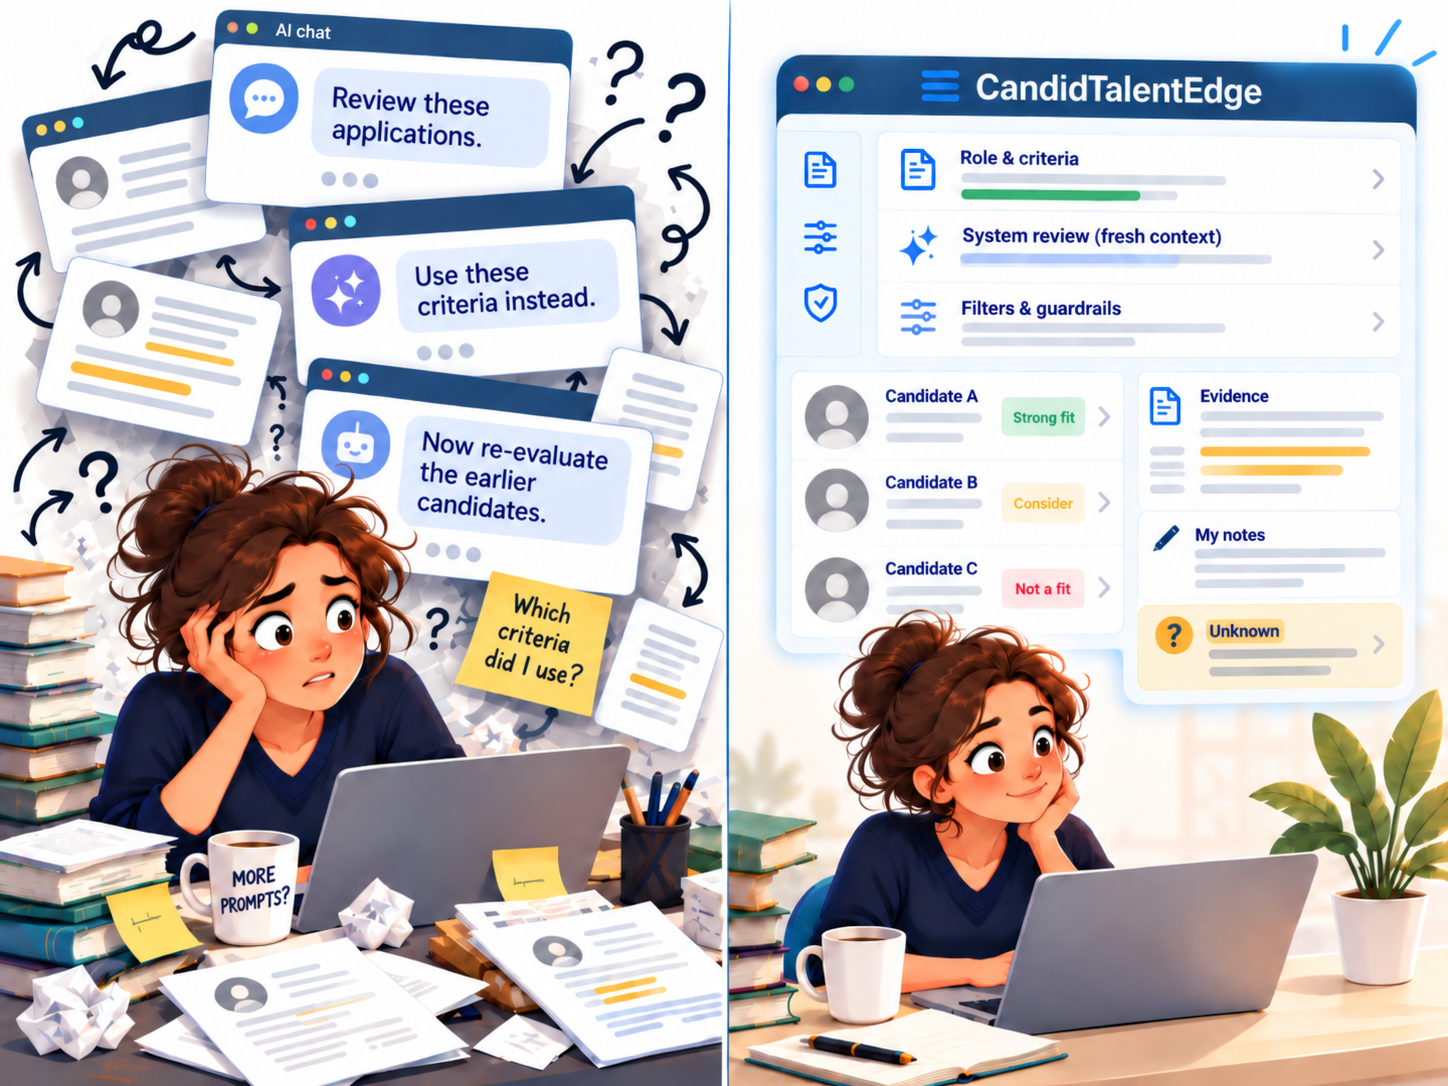
You can ask either to review applications. For an occasional review, that may be enough. CandidTalentEdge gives you a repeatable process for reviewing a whole applicant pool.
Each candidate gets a fresh review context.
The app prepares each evaluation with the role, the candidate’s information, and your approved criteria. Reviews do not accumulate in one long conversation with earlier applicants. AI can still make mistakes, so the evidence remains available for you to check.
Filters reflect what you need from the role.
When you disagree with a finding, use that judgment to refine your screening criteria. Guardrails flag potential discrimination risks and questionable wording, and can suggest clearer ways to express what you need. You approve the wording and consequence before use. If your criteria change, you can re-evaluate earlier applicants.
Your findings and decisions stay organized.
Inspect the evidence behind each finding and record your decision separately from the system rating. The AI evaluates the evidence against your filters, and the app applies the consequence you saved.
You can build a similar process around a chat tool, but you have to maintain the instructions, organize the results, track your decisions, and check that the criteria are being applied consistently. CandidTalentEdge brings that work together.
What to know before you use it.
How candidate data is handled, where AI can fall short, and what you remain responsible for.
Local records. AI processing through your OpenAI project.
Candidate and job records stay on your computer. CandidTalentEdge does not collect or store candidate screening content on its servers. Content needed for parsing and evaluation is sent to OpenAI using your API key; local storage does not mean AI processing happens on your Mac.
Read how data is handledAI results need your review.
CandidTalentEdge checks whether evaluation responses follow the required structure, include the necessary evidence and reasoning, and give consistent conclusions. If scoring or screening-filter evaluation fails these checks, the result is marked “Unable to evaluate” rather than used to rank the candidate. You can retry the evaluation or review the candidate yourself.
In more than a year of using and evaluating CandidTalentEdge, I’ve found these failures useful warning signs. They have prompted me to investigate model limitations, clarify vague job descriptions, and resolve conflicting screening criteria. A failed check does not identify the cause, but making it visible gives you a starting point for addressing the problem instead of relying on a result that should not have passed.
These checks catch some failures to follow instructions, but cannot guarantee a correct interpretation. Supporting evidence remains available for you to inspect, and the hiring decision remains yours.
Screening guardrails do not eliminate bias.
Screening-filter guardrails flag potential discrimination risks and questionable wording. Some warnings require a written justification before a filter can be saved. These checks do not eliminate bias. You remain responsible for fair decisions and your legal obligations.
Read the termsTry it on a role you know.
Add a job description and review your current applicants. Compare the findings with your own judgment and check whether they help you spot useful experience or prepare better interview questions.
In my own hiring, a review has sometimes revealed that the job description did not reflect what we actually valued. The trial can help you examine the role as well as the candidates.
You can begin without custom filters and add them as you review candidates and clarify which job requirements matter most.
For Apple Silicon Macs. 14 days or 50 completed evaluations, whichever comes first. A Pro license activates on up to three of your Macs.
Your own OpenAI API key is required; OpenAI usage costs are separate.